Artificial intelligence is rapidly moving beyond text. Today’s most powerful models don’t just read—they see, hear, and interpret the world through multiple lenses simultaneously . This shift means that the data fueling AI is changing just as fast. Instead of tidy spreadsheets, we have video clips with audio tracks, social media posts with embedded images, and sensor feeds with synchronized timestamps.
Training AI to handle this complexity requires a fundamentally different approach to data preparation. Traditional single-modality labeling—like tagging an image or classifying a text document—falls short when your goal is to teach a model how a cat looks and sounds, or how a sarcastic comment pairs with an eye-roll emoji. This is the frontier of multimodal data annotation, and it presents unique challenges and opportunities.
The global data annotation market is projected to reach $143.5 billion by 2032, growing at over 37% annually, driven by demand for complex multimodal datasets . This isn’t just about more data; it’s about more types of data working together. But how do you label across different formats effectively? Let’s break down the practical steps.
What Exactly Is Multimodal Annotation?
Multimodal annotation, in a nutshell, is the process of labeling data across two or more different formats within a single, unified dataset. Think of it like this: instead of having separate files for an image and its description, you create a single annotation record that links the visual elements to the corresponding text . This creates a richer, more contextual training example.
For instance, you might have a 30-second video clip of a construction site. A multimodal annotation task wouldn’t just ask for a label like “excavator” for a single frame. It might ask you to:
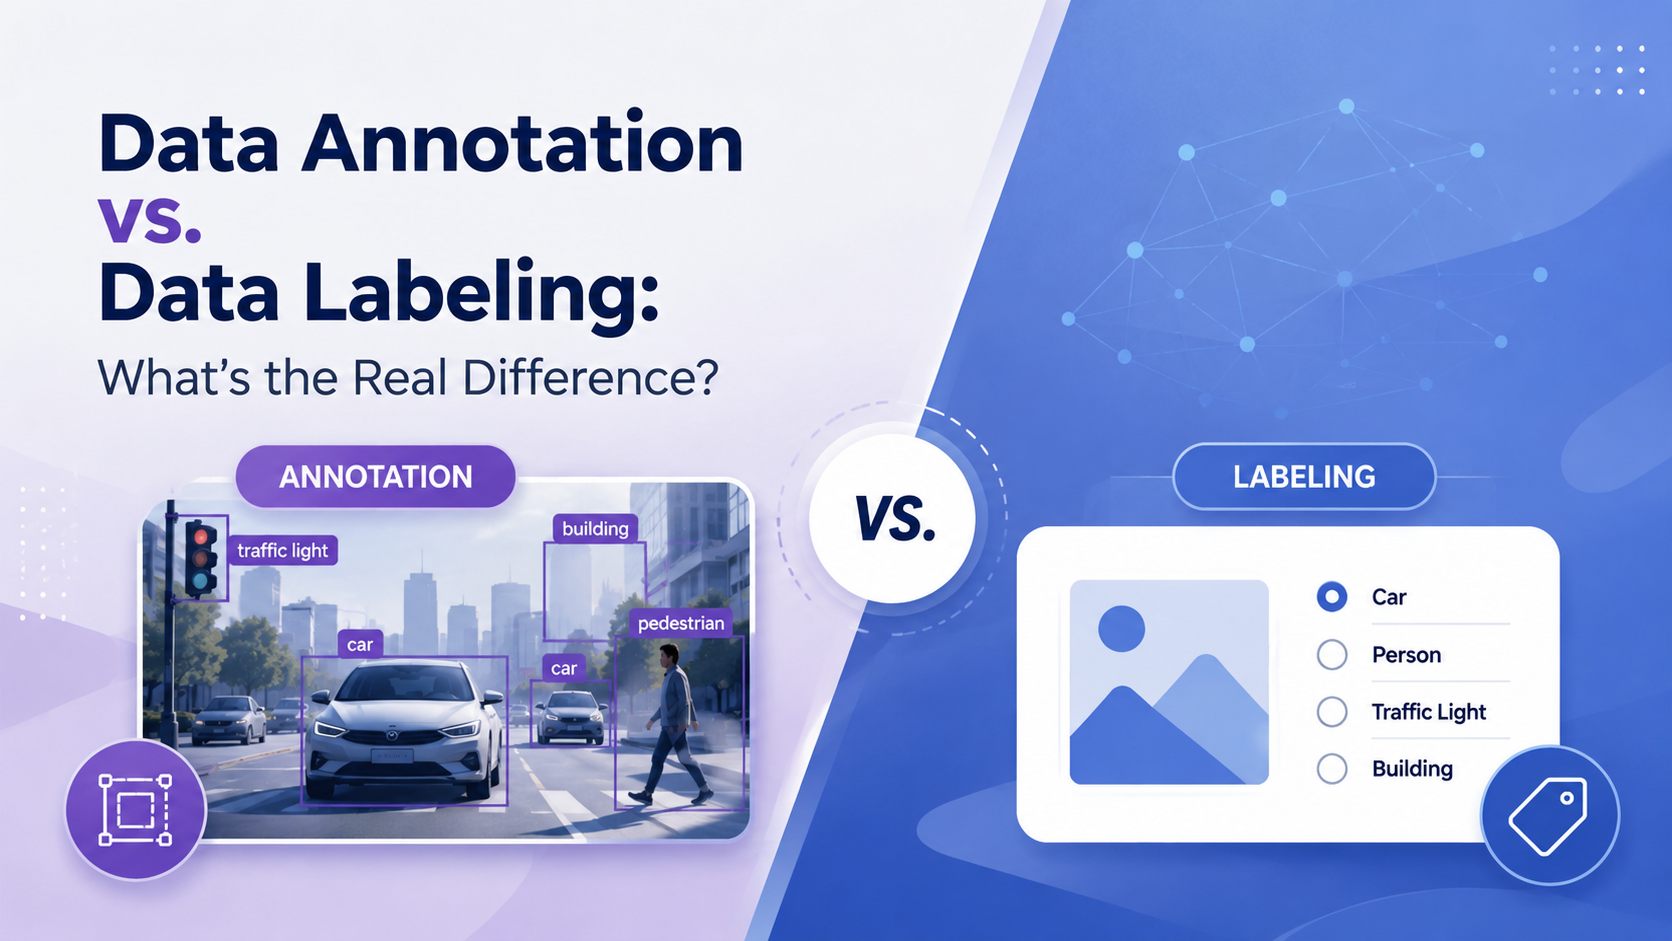
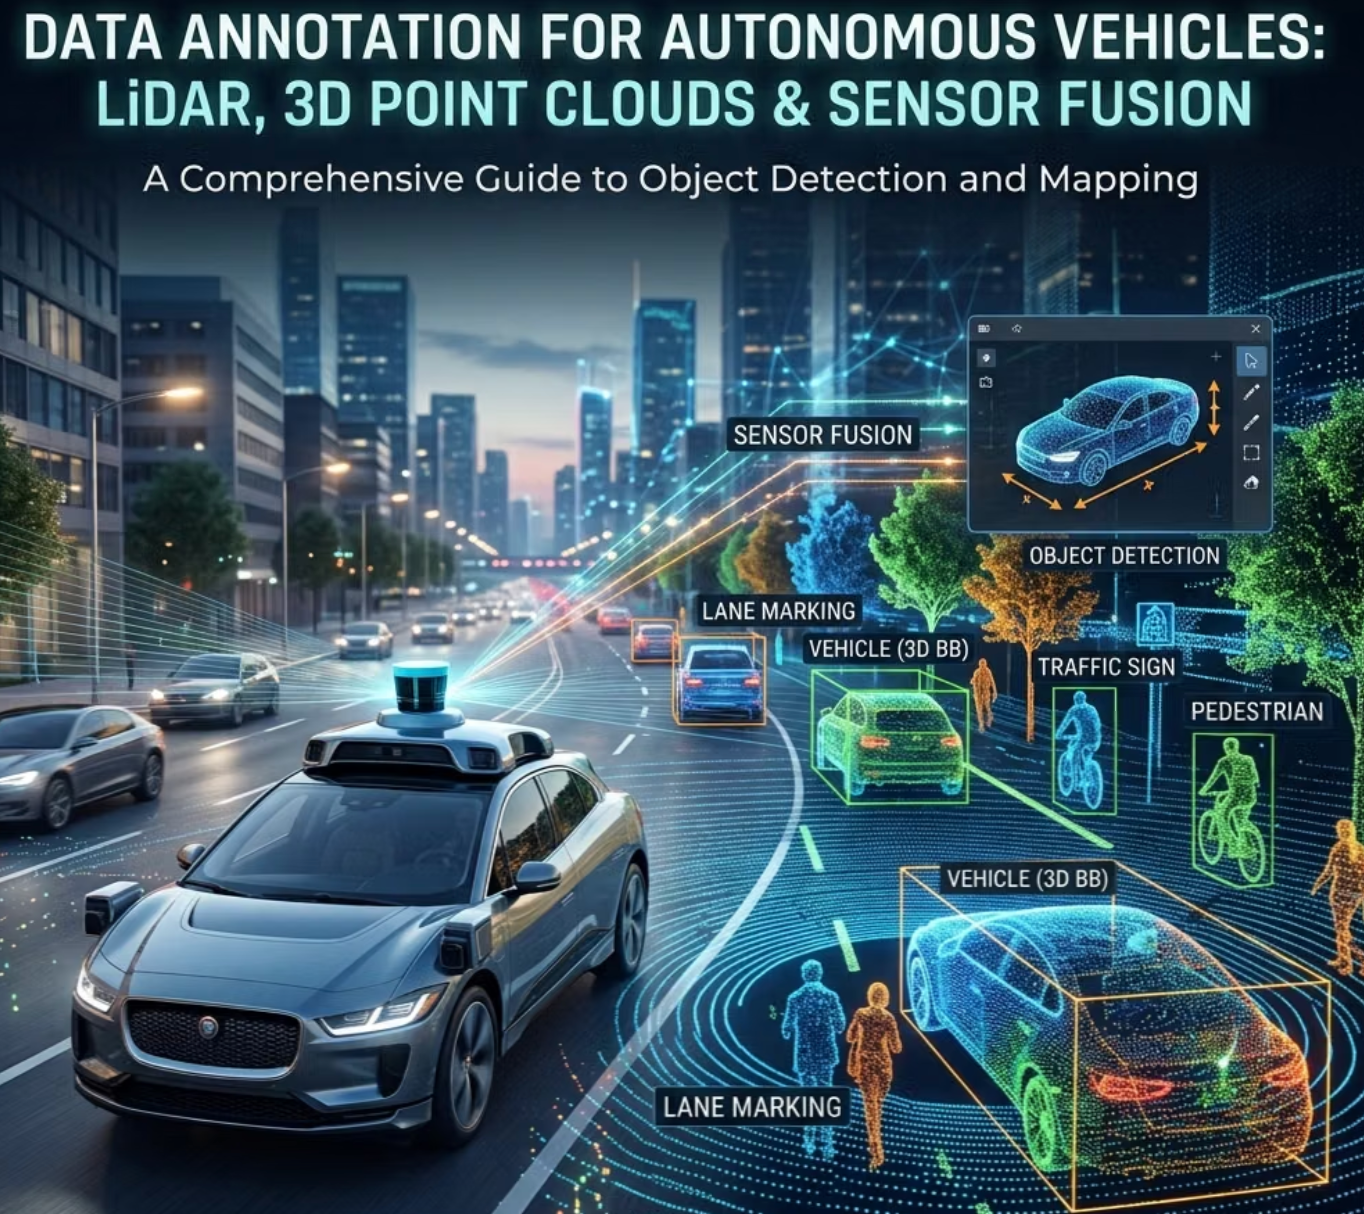
- Annotate the bounding boxes around the excavator in the video frames.
- Transcribe the audio of the engine.
- Add a tag describing the time-based action (“loading dirt”).
- Align all this information so the model learns to connect the visual, the sound, and the action.
The goal is to create a cohesive dataset that reflects how information naturally exists in the real world .
Why Bother with Multimodal Labeling?
The primary reason to invest in multimodal annotation is performance. A model trained on multimodal data understands nuance and context much better than one trained on text alone. A 2025 study from researchers at NYU and Vanderbilt found that giving human coders access to a social media post’s full content—images, links, and metadata—significantly improved the accuracy of their labels compared to just reading the text . This is because images and videos often add essential context that clarifies ambiguous language.
However, this superior performance comes at a cost. The same study highlighted that multimodal data is more expensive to collect, store, and manually label. It can take human annotators longer to process a video with audio than a simple text post . The key, therefore, is to be strategic and measure whether the improved quality justifies the increased cost.
The Basic Workflow
A typical multimodal annotation project is more complex than a single-modality one. It’s a multi-stage process:
- Data Preparation: This involves cleaning and organizing raw inputs—images, videos, text, or audio—so they can be displayed and labeled in a consistent way .
- Annotation: Specialized tools allow annotators to view and label multiple data types at the same time, such as an image with its associated text . This is the core task where the labels are applied.
- Alignment: This is the crucial step that differentiates multimodal from single-modality annotation. Here, you ensure that elements across modalities correspond correctly. For example, you must match the right subtitle to the right video frame or link a caption to a specific region in an image . A misalignment here will confuse your model.
- Quality Control: Your dataset needs to be checked for consistency and accuracy. Mistakes in one modality can compound and cause errors in others. Techniques like cross-modality validation—where you check that text descriptions match the visual content—are essential.
- Integration: Finally, all the labeled data from the different modalities is combined into a single structured format, like JSON or a specialized COCO-style schema, that can be used for model training.
Choosing the Right Tools
Not all annotation platforms are built for multimodal work. When selecting a tool, consider its ability to support all the data types you need, its AI-assisted labeling features (like pre-labeling), workflow management, and how well it can integrate with your existing machine learning pipeline. According to comparisons from platforms like Roboflow, three leading tools in this space are Roboflow, Labelbox, and SuperAnnotate . Roboflow, for instance, now offers a specialized project type for pairing images with text prompts, ideal for visual question answering (VQA) tasks . Labelbox provides an integrated workspace with a flexible ontology and attachment system for managing complex multimodal data . SuperAnnotate offers similar capabilities with pre-built templates for common vision-language tasks .
How to Manage the High Costs of Multimodal Data
Given the increased expense, how can you keep your project within budget? Here are a few actionable tips:
Prioritize AI-Assisted Pre-Labeling. Modern tools let you use AI to generate initial labels, which human annotators then correct . A 2025 paper on the “ACT as Human” data pipeline demonstrated that this approach, where AI flags potentially erroneous labels for human review, can reduce human costs by up to 90% while maintaining performance .
Use Smart Sampling. When a human review is needed, don’t review random samples. Implement an active learning workflow where your AI model identifies the most ambiguous or uncertain data points for human annotation . This focuses human effort where it is most valuable. For example, the “ACT” pipeline specifically samples data points where the AI annotator is likely to have made a mistake, ensuring human review is used efficiently .
Optimize for Your End Goal. Not all multimodal tasks require the same level of complexity. The NYU study found that the benefits of multimodal labels for training a text-only downstream classifier were not always clear . The quality of the human labels might improve, but if the final model only reads text, the investment in visual data might not pay off in model performance. Always consider your final model’s architecture.
The Tools of the Trade
The market offers a range of solutions for multimodal annotation, from open-source platforms to enterprise-level services. A good platform should be able to import, display, and label all the data types your project requires, ideally within a single interface.
| Feature | Roboflow | Labelbox | SuperAnnotate |
| Key Modalities | Images, Text (for VQA) | Images, Text, Video, Audio, Geospatial | Images, Video, Text, Audio |
| Key Strength | User-friendly, strong computer vision workflow, easy export | Powerful workflow management, flexible ontology, enterprise-ready | End-to-end platform with automation and model evaluation |
| Best For | Vision-language projects (like image captioning) | Complex, large-scale, multimodal enterprise projects | Teams needing automation and a complete data pipeline |
The Role of AI in Improving Efficiency
The high cost and complexity of multimodal annotation are driving innovation. Agentic AI frameworks, like AURA (Agentic AI for Unified Reliability Modeling and Annotation Aggregation), are now being developed to automate parts of the process. AURA coordinates multiple AI agents—each with different strengths—to generate and validate labels without needing human-verified ground truth . This approach uses statistical modeling to estimate each agent’s reliability and infer high-confidence labels, achieving accuracy improvements of up to 5.8% over baselines . While full automation is still a future goal, these models are already making the annotation pipeline more efficient.
Conclusion
Multimodal data annotation is no longer a niche requirement; it’s becoming the standard for building advanced, reliable AI systems . It is a much more complex undertaking than traditional single-modality labeling, requiring specialized tools and a strategic approach to manage its higher costs. However, the payoff is a model that understands the world with greater nuance and accuracy. By using AI-assisted pre-labeling, smart sampling, and careful workflow design, teams can navigate these challenges and build the rich datasets needed for the next generation of artificial intelligence.